
 The Specialty News
Alibaba Ships Qwen4-Max, a 2.4-Trillion-Parameter Model at $1.50 per Million Tokens
The new Qwen flagship reads up to a million tokens at once and, by Alibaba's count, finishes the average task for about 60% less than the model it replaces.
Alibaba's biggest model yet has 2.4 trillion parameters and wakes up only 71 billion of them for each word it writes. Qwen4-Max went on general release on Monday, November 16, through the QwenCloud API, priced at $1.50 per million input tokens and $4.50 per million output tokens. For developers building agents, that is a frontier-sized model with a one-million-token memory at a price that makes long jobs affordable.
71 Billion Awake Out of 2.4 Trillion
Qwen4-Max is a mixture-of-experts model: a huge network split into specialists, of which only a small team works on any given word. Alibaba says it keeps the same 2.4 trillion total parameters as Qwen3.8-Max but activates 25% fewer of them per token, 71 billion. It reads text, images and video natively, and its context window holds one million tokens.
The price is set for heavy use. At $1.50 per million input tokens, having the model read a 300-page book costs roughly 20 cents, and repeated input that the system caches drops to $0.075 per million. Alibaba says every price is lower than its previous flagship, with cached input 70% cheaper.
The bigger saving, according to Alibaba, comes from the model using fewer words to get a job done. On Work360, its in-house test of real tasks across 721 specialized fields, Qwen4-Max beat Qwen3.8-Max overall while using 35% fewer tokens at its High reasoning setting, cutting the average cost per task by around 60%.
Those are Alibaba's own measurements. Its scoreboard against the American labs tells a more detailed story.
Where It Leads Opus 5.5, and Where It Trails
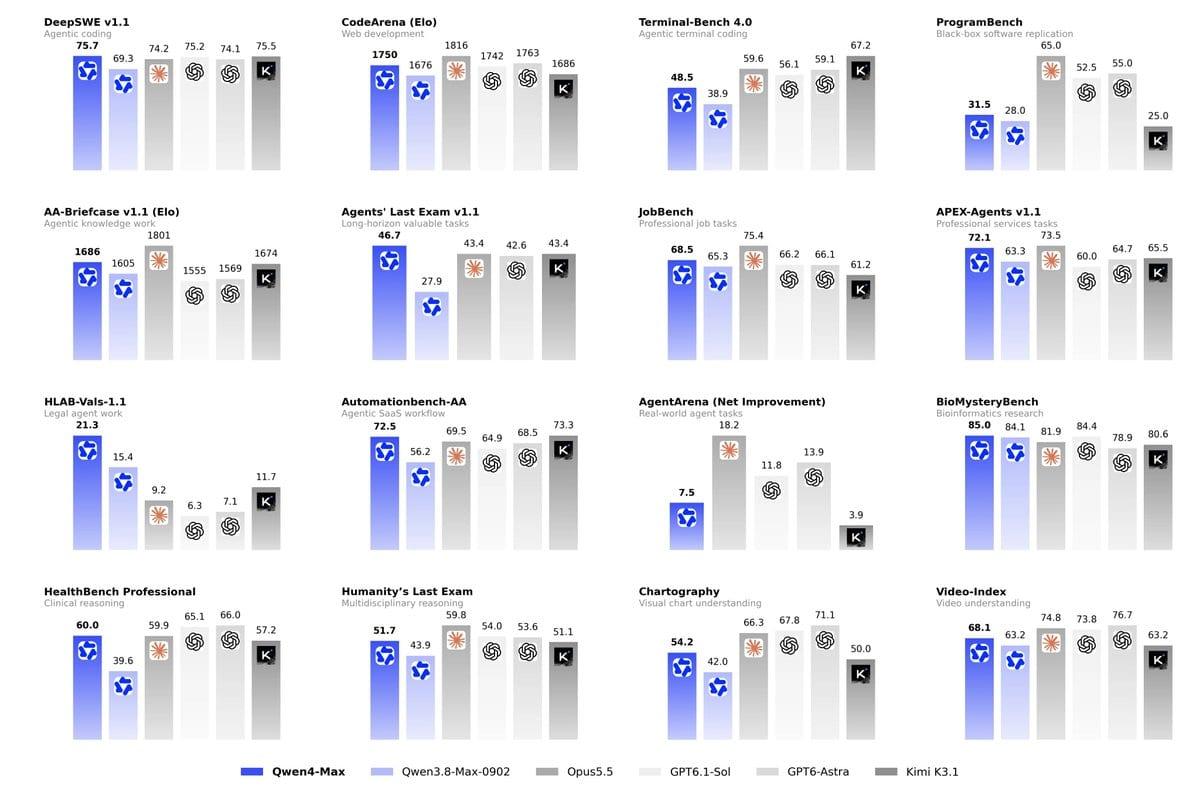
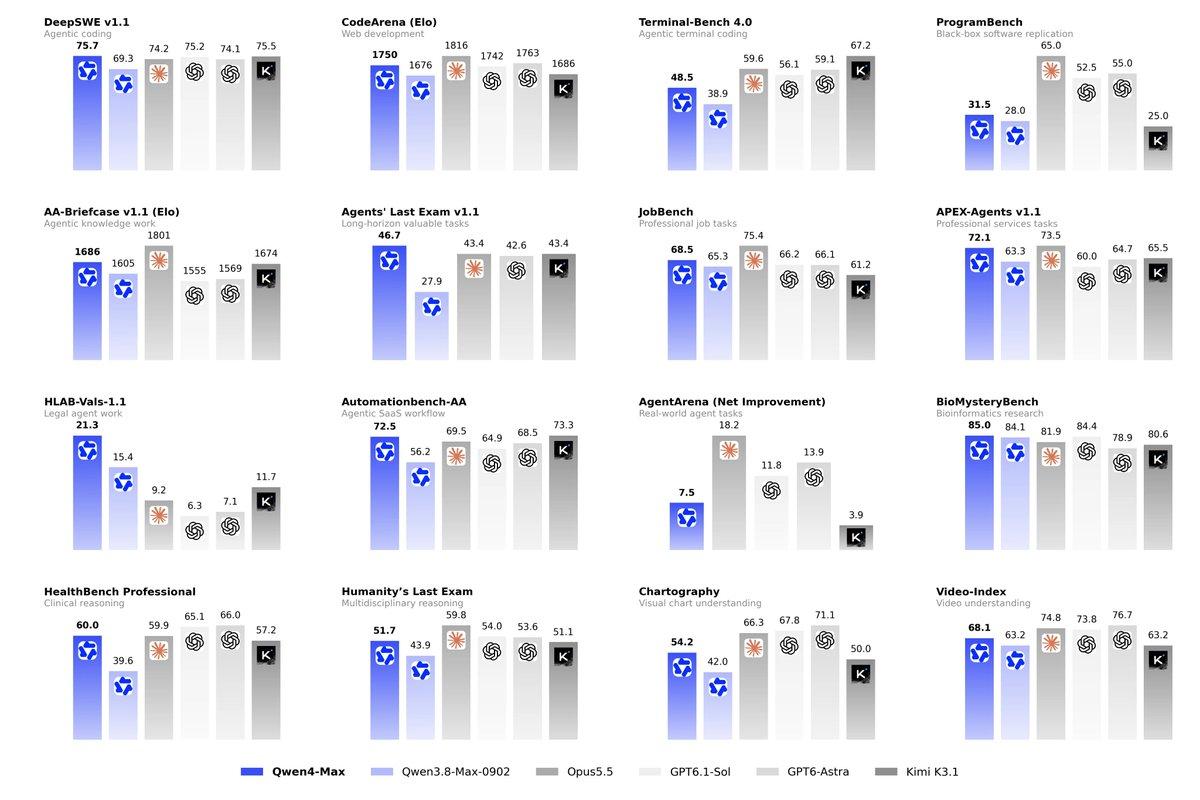
In the benchmark chart Alibaba published with the launch, Qwen4-Max is compared with Anthropic's Opus 5.5, OpenAI's GPT-6.1 Sol and GPT-6 Astra, and Moonshot's Kimi K3.1. It comes out ahead of Opus 5.5 on several agent tests: 75.7 against 74.2 on DeepSWE for agentic coding, 46.7 against 43.4 on Agents' Last Exam for long, valuable tasks, and 85.0 against 81.9 on BioMysteryBench for bioinformatics research. On a legal agent test, HLAB-Vals, it scores 21.3 to Opus 5.5's 9.2.
It also shows where the work is left to do. On Terminal-Bench 4.0, which measures coding agents working in a command line, Qwen4-Max scores 48.5 against 59.6 for Opus 5.5 and 67.2 for Kimi K3.1. On Humanity's Last Exam it posts 51.7 to Opus 5.5's 59.8, and on Code Arena, a public leaderboard of real coding, Alibaba says it ranks sixth.
An early independent reading points the same way: Artificial Analysis gave it 43 on its Intelligence Index, above the median of 41 for comparable models. The more telling evidence may be what Alibaba says it has already done with it.
From 475 Minutes to 24, and the Open Models Still to Come
Alibaba's launch post lists the jobs it has put Qwen4-Max to. In car manufacturing, it says the model cut the time to program a workpiece by hand from roughly 475 minutes to 24. In a 48-hour unattended agent run, it produced a coolant molecule that was then validated in experiments. In Alibaba's own cloud, it made offline CPU rescheduling more than 14 times faster.
The model is available now through QwenCloud's API and its Token Plan subscriptions, in the QwenWork app and in Qwen Studio. Its weights are not public: Qwen4-Max runs only on Alibaba's servers. The company has promised that smaller members of the family will follow in the open.
“Open-weight, smaller-scale models from the Qwen4 series will soon be released to developers worldwide.”— Alibaba
For a startup running agents around the clock, the arithmetic changes today: a model with a million-token memory, at $1.50 per million tokens, that finishes more of the job with fewer words.
What people are saying

“📢 Meet Qwen4-Max, your new AI teammate for work, creativity, and discovery! Qwen4-Max is built on a new MoE architecture with native vision and a 1M-token context window. Highlights: - Outperforms Qwen3.8-Max with up to ~50% fewer tokens, while average cost per task drops over”
Neck and Neck With Opus 5.5
The Brief
Stay curious
AI and technology: what changes and why it matters.
Your daily selection, in English or Spanish.
Free forever. Unsubscribe anytime.
More stories
Conversation
Start the conversation